Hi, I'm Michael
Web Scraping Engineer
You give me the targets. I deliver the data.
I build automated extraction systems that collect structured data from public websites. My systems handle JavaScript-heavy websites, browser and TLS fingerprinting, Cloudflare, Akamai, CAPTCHAs, and other common scraping challenges.
I deliver clean, structured data in formats such as JSON, CSV, Excel, Google Sheets, and databases, ready for business use.
Our Services
Web Scraping & Automation Solutions
Custom Web Scraping Systems
Extract structured data from complex JavaScript-heavy websites, marketplaces, and dynamic platforms, including APIs, hidden endpoints, and structured JSON sources. Built to handle TLS fingerprinting, Cloudflare, Akamai and authentication reliably.
Automated Price & Competitor Intelligence
Develop automated monitoring systems for e-commerce products and real estate listings, tracking price changes, inventory or listing status, and competitor activity across multiple channels, with real-time alerts for significant market events.
Business Directory & Lead Data Extraction
Automate the collection of business listings, contact information, and public company data from directories and websites like Google Maps, Yellow Pages, and more into clean, structured datasets.
Complex PDF Extraction
Extract tables, records, and text from PDFs, scanned files, invoices, reports, and business documents.
Python Automation
Create end-to-end automation workflows for recurring data collection, scheduling, and direct delivery into clean CSV, Excel, JSON, or database formats.
Industries Covered
Industries We Serve
Real Estate
Capture up-to-date real estate data, live foreclosure listings, agent details, and historical pricing changes directly from regional marketplaces and property portals, delivered in clean, structured format, no manual tracking.
Retail & E-Commerce
Extract live product variations, inventory stock levels, and real-time competitor pricing changes on a continuous schedule, with competitor datasets mapped by SKU for faster pricing decisions.
B2B Directories & Data Aggregators
Extract public business listings, company profiles, contact information, and local business directories automatically into structured datasets, no manual copy-pasting.
Featured Projects

PriceVecta is an automated price-monitoring platform that continuously tracks product prices and stock availability across client-specified e-commerce, retail, and distributor websites. It delivers real-time Telegram and email alerts when changes are detected while centralising historical data, pricing activity, and CSV exports into a single dashboard. PriceVecta helps businesses react faster to competitor pricing, monitor supplier changes, and make informed pricing decisions using up-to-date market data.

Foreclosure listings change constantly as auctions are scheduled, postponed, cancelled, or sold, making manual tracking repetitive and time consuming, often leading to missed opportunities. This automated monitoring system collects active foreclosure listings from Auction.com on a scheduled basis, standardises the data, and delivers structured datasets for property sourcing, market monitoring, historical tracking, ROI analysis, and investment decision-making. By using API Reverse Engineering to extract structured listing records, it eliminates the overhead of browser automation.

This system automates the collection of property listings from Movoto by navigating search results, collecting listing URLs, and extracting structured property information from individual listing pages. The system supports configurable search locations, handles pagination, synchronises with dynamic page content using explicit Playwright waits, and exports clean, structured datasets for real estate research, market analysis, and property monitoring.
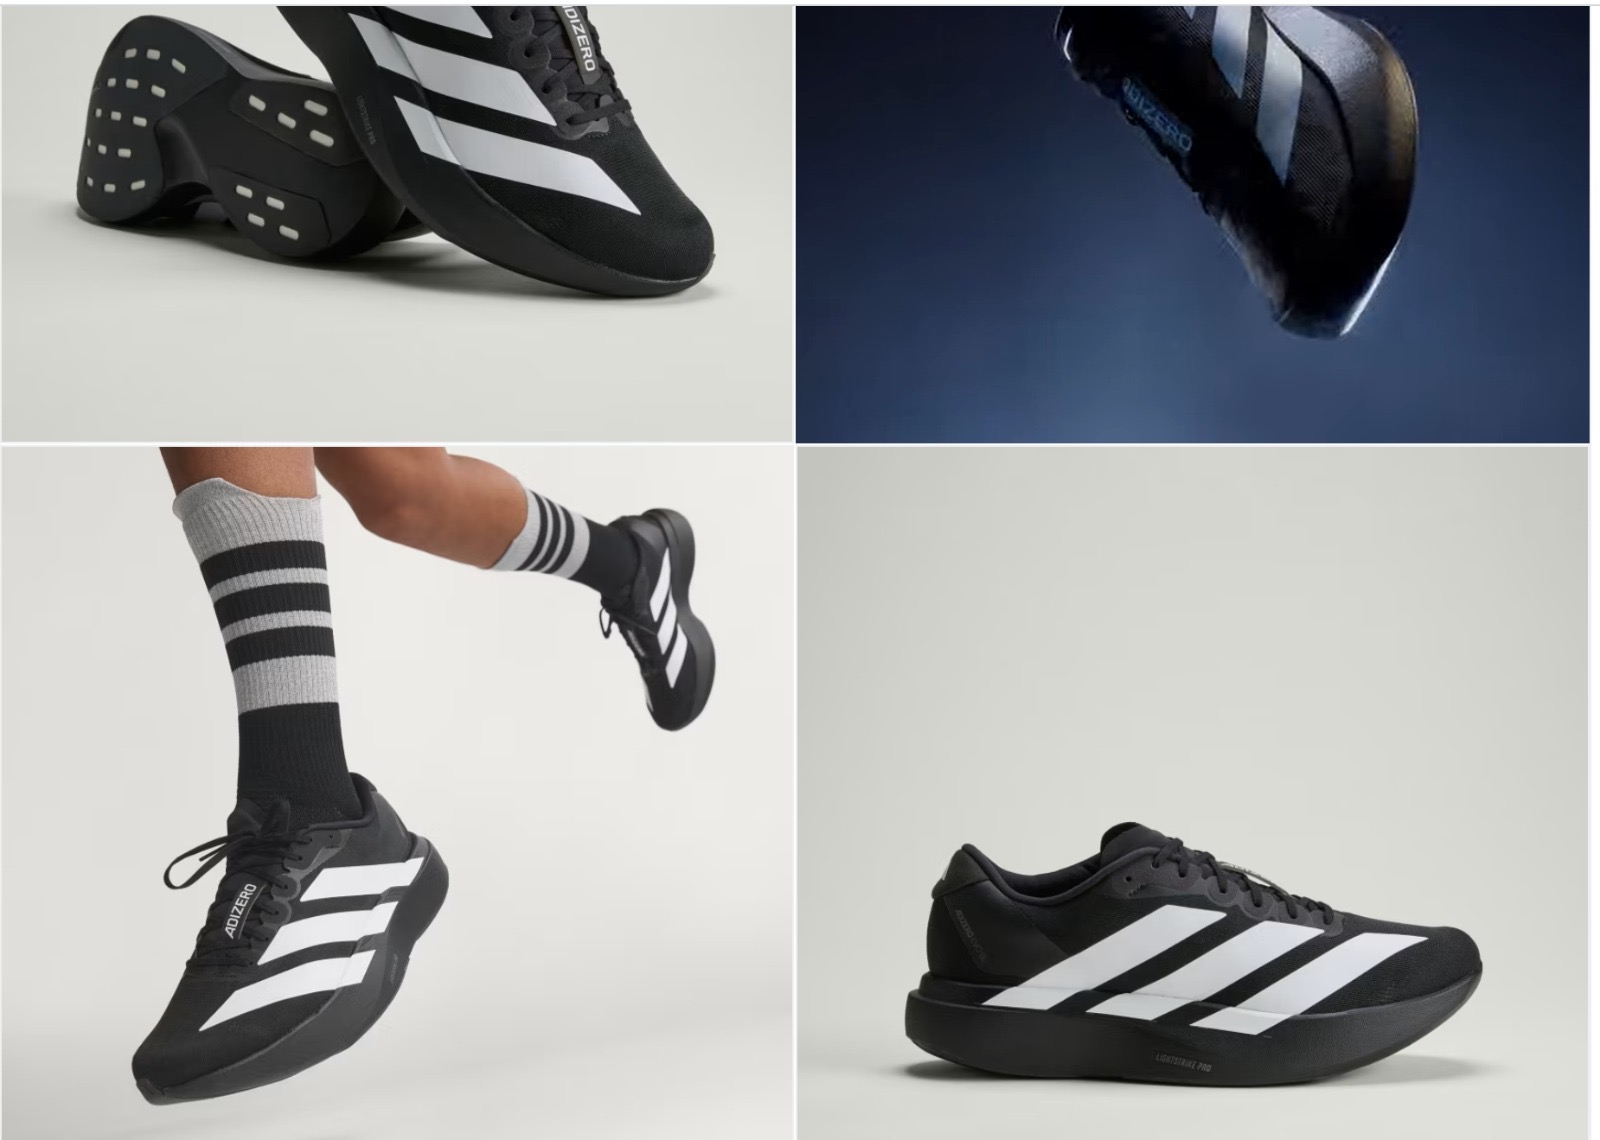
This system collects structured men's sneaker product data from Adidas through API reverse engineering, covering 1,101 product listings and extracting pricing, ratings, model numbers, images, colour variations, product URLs, and other product attributes. The collected data is standardised and exported as CSV for product research, price monitoring, catalogue analysis, and competitor tracking.

A fully automated Python and Playwright price monitoring system that tracks Samsung Galaxy A06 listings on Jumia Nigeria daily via GitHub Actions. The pipeline detects price changes, maintains historical datasets, and automatically classifies new, increased, decreased, and unchanged listings. Built for reliable, unattended operation, it provides continuous pricing intelligence to support competitor monitoring, pricing strategies, and informed business decisions.
All Projects
My Recent Projects

Configurable system that extracts structured real estate listings using search filters for location, listing type, and bedroom count.

Daily automated tracking of price, stock, and ratings changes, producing a validated dataset for trend analysis.

Scrapes UK property auction listings across multiple categories, extracting property and auction details from listing pages.

Extracts whisky product data directly from The Whisky Exchange’s internal search API.

Parameterised scraper that extracts real estate and foreclosure listings using JSON-LD and TLS fingerprinting for anti-bot protection.

Collects detailed luxury property listings across a market, built to adapt easily to new cities.

Simulates real browser behavior to reliably extract product data from a dynamic, JavaScript-rendered site.

Segmented nearly 43,000 transactions into customer value tiers to reveal revenue trends and support growth strategy.

Built a churn-prediction model that flags at-risk customers early, enabling proactive retention decisions.

Forecasted natural gas prices using seasonal trend modeling to support storage and trading decisions.
About Me

I’m a Web Scraping Engineer focused on building reliable, automated extraction systems that pull data from websites, PDFs, and APIs, then clean and structure it into usable formats such as CSV, Excel, Google Sheets, and databases.
I build solutions for competitor monitoring, change detection, price tracking, inventory monitoring, lead generation, market research, supply chain data, and automated web data collection that support business decision-making
I handle JavaScript-rendered content, browser and TLS fingerprinting, Cloudflare and Akamai, CAPTCHAs, and other common scraping challenges. Where possible, I reverse engineer APIs to reduce overhead and use PDF and OCR tools for complex document extraction. When needed, I build Flask applications to make extracted data easier to search, monitor, and use.
My approach is shaped by my background in mathematics and years of teaching, which trained me to break down problems and choose the most efficient solution, whether through API access, browser automation, or HTML parsing.
The result is simple: cleaned, structured, reliable data delivered in the format you need.
If you’re working with data that’s difficult to collect or organise, I can help simplify it.
My Skills
My Technical Skills
Web Scraping & Automation
- Python
- Web Scraping
- Data Extraction
- API Reverse Engineering
- Scrapy
- Playwright
- BeautifulSoup
- SeleniumBase
- Requests
- TLS Fingerprinting
- Python Automation
- Linux Cron
- GitHub Actions
- Complex PDF Parsing
Backend & Deployment
- Flask
- SQLAlchemy
- SQL
- PostgreSQL
- SQLite
- Docker
- Google Cloud
- GCP Compute Engine
- API Integration
Data Processing & Output
- Pandas
- Microsoft Excel
- Google Sheets
Frontend
- JavaScript
- HTML
- CSS
- Bootstrap
What Clients Say
My Experience
My Work Experience
Experience in The Field
Portfolio of Projects
Satisfied Customers
Available for freelance & contract work — Let's talk